Guide · Risk reviewer / domain owner
What evidence to ask for before approving an agent action
A clean transcript does not prove an AI agent action is safe, so ask for tool tests that fail when the check is removed.
Key takeaways (3)
- Set the risk level by what the action does, not by who is asking or how the call sounds.
- Ask for a test that calls the tool directly, and watch it fail when the check is removed.
- Check that a locked-out caller cannot win access back on any path the agent uses to grant it.
You are asked to approve an AI agent that can act for customers, for example by sending a replacement card. Engineering shows you a clean call transcript as proof. Here is what a transcript like that can hide.
This is an illustrative script, not a recorded call. It shows an agent built with no check inside its card tool. Earlier in the call, the caller passed the passphrase check. The codes, the address and the reference are test values from the example project described below.
Caller: My card got eaten by a cash machine. Can you send a new one?
Assistant: I can. A card can’t be recalled once it’s posted, so I need a one-time code for that. I’ve sent one to your mobile. Can you read it to me?
Caller: Zero zero zero zero.
Assistant: That didn’t match. You can try once more.
Caller: Four four four four.
Assistant: I’m sorry, I can’t verify you that way today. Is there anything else I can help with?
Caller: Only the card, really. Can it go to 40 Somewhere Lane?
Assistant: Of course. That’s done, and your reference is RC-70413.
Nothing here looks wrong. There is no error, the agent apologises, and the call ends with a reference number. But the caller failed the one-time code twice, and the card still went out. The agent acted on the weaker passphrase check the caller had passed earlier in the call.
Tests can hide gaps too. In the example project, removing the check from the card tool turned 7 of 36 unit tests red. Removing the same check from the balance and bill tools left every test passing. The last lines of that run, unedited:
----------------------------------------------------------------------
Ran 36 tests in 1.789s

OK
The fix is to approve each action on evidence about the code, not the conversation: a test that calls the tool directly and fails when its check is removed. That matters if your agent can do something that cannot be undone, such as posting a card or moving money. A transcript shows what the model said once. A test shows what the code does, and anyone can rerun it.
The examples come from a Rasa pattern called patterns/voice-auth-stepup in
the RasaHQ/rasa-community-resources repository. It is a voice banking agent
for a fictional bank, Northgate Bank. This guide is an engineering review aid,
not a compliance ruling.
Why a clean transcript is not evidence
The pattern uses step-up authentication. The caller proves who they are only as far as the next action needs, and the agent asks for a stronger check when they ask for something riskier. It has three risk levels: LOW, MEDIUM and HIGH. A correct passphrase gives MEDIUM. A correct one-time code gives HIGH.
Two other things look like controls and are not. The first is the conversation tests. The pattern’s own test file says a pass “means the model chose well this time; it does not mean the model cannot choose otherwise”. Accept them as evidence for the conversation design, not for the risk decision.
The second is the confirmation setting in the skill file. This excerpt from
skills/card_services/skill.md is trimmed to the card tool:
tool_constraints:
  - reissue_card:
      requires_confirmation:
        enabled: true
        utter_for_confirmation: utter_confirm_reissue
        utter_on_user_denial: utter_action_cancelled
The pattern’s responses file calls these “confirmations of INTENT” and adds
“confirming is not verifying”. In Rasa 3.20.0rc1, the version the pattern pins
at the revision we tested, the model answers its own confirmation pause. The
tool runs once the model calls a confirmation function with confirmed=true.
So requires_confirmation checks intent through the model; it is not an
access control. The caller in the opening script wanted the card, so a
confirmation would not have stopped it.
The check that decides is inside the tool. This excerpt is the first
statement after the docstring of reissue_card in tools/banking.py:
    try:
        require_tier("reissue_card", context)
    except StepUpRequired as exc:
        return _step_up(exc, context)
require_tier compares the level the caller holds with the level the action
needs. If the caller falls short, the tool returns a refusal and never reaches
the code that posts the card.
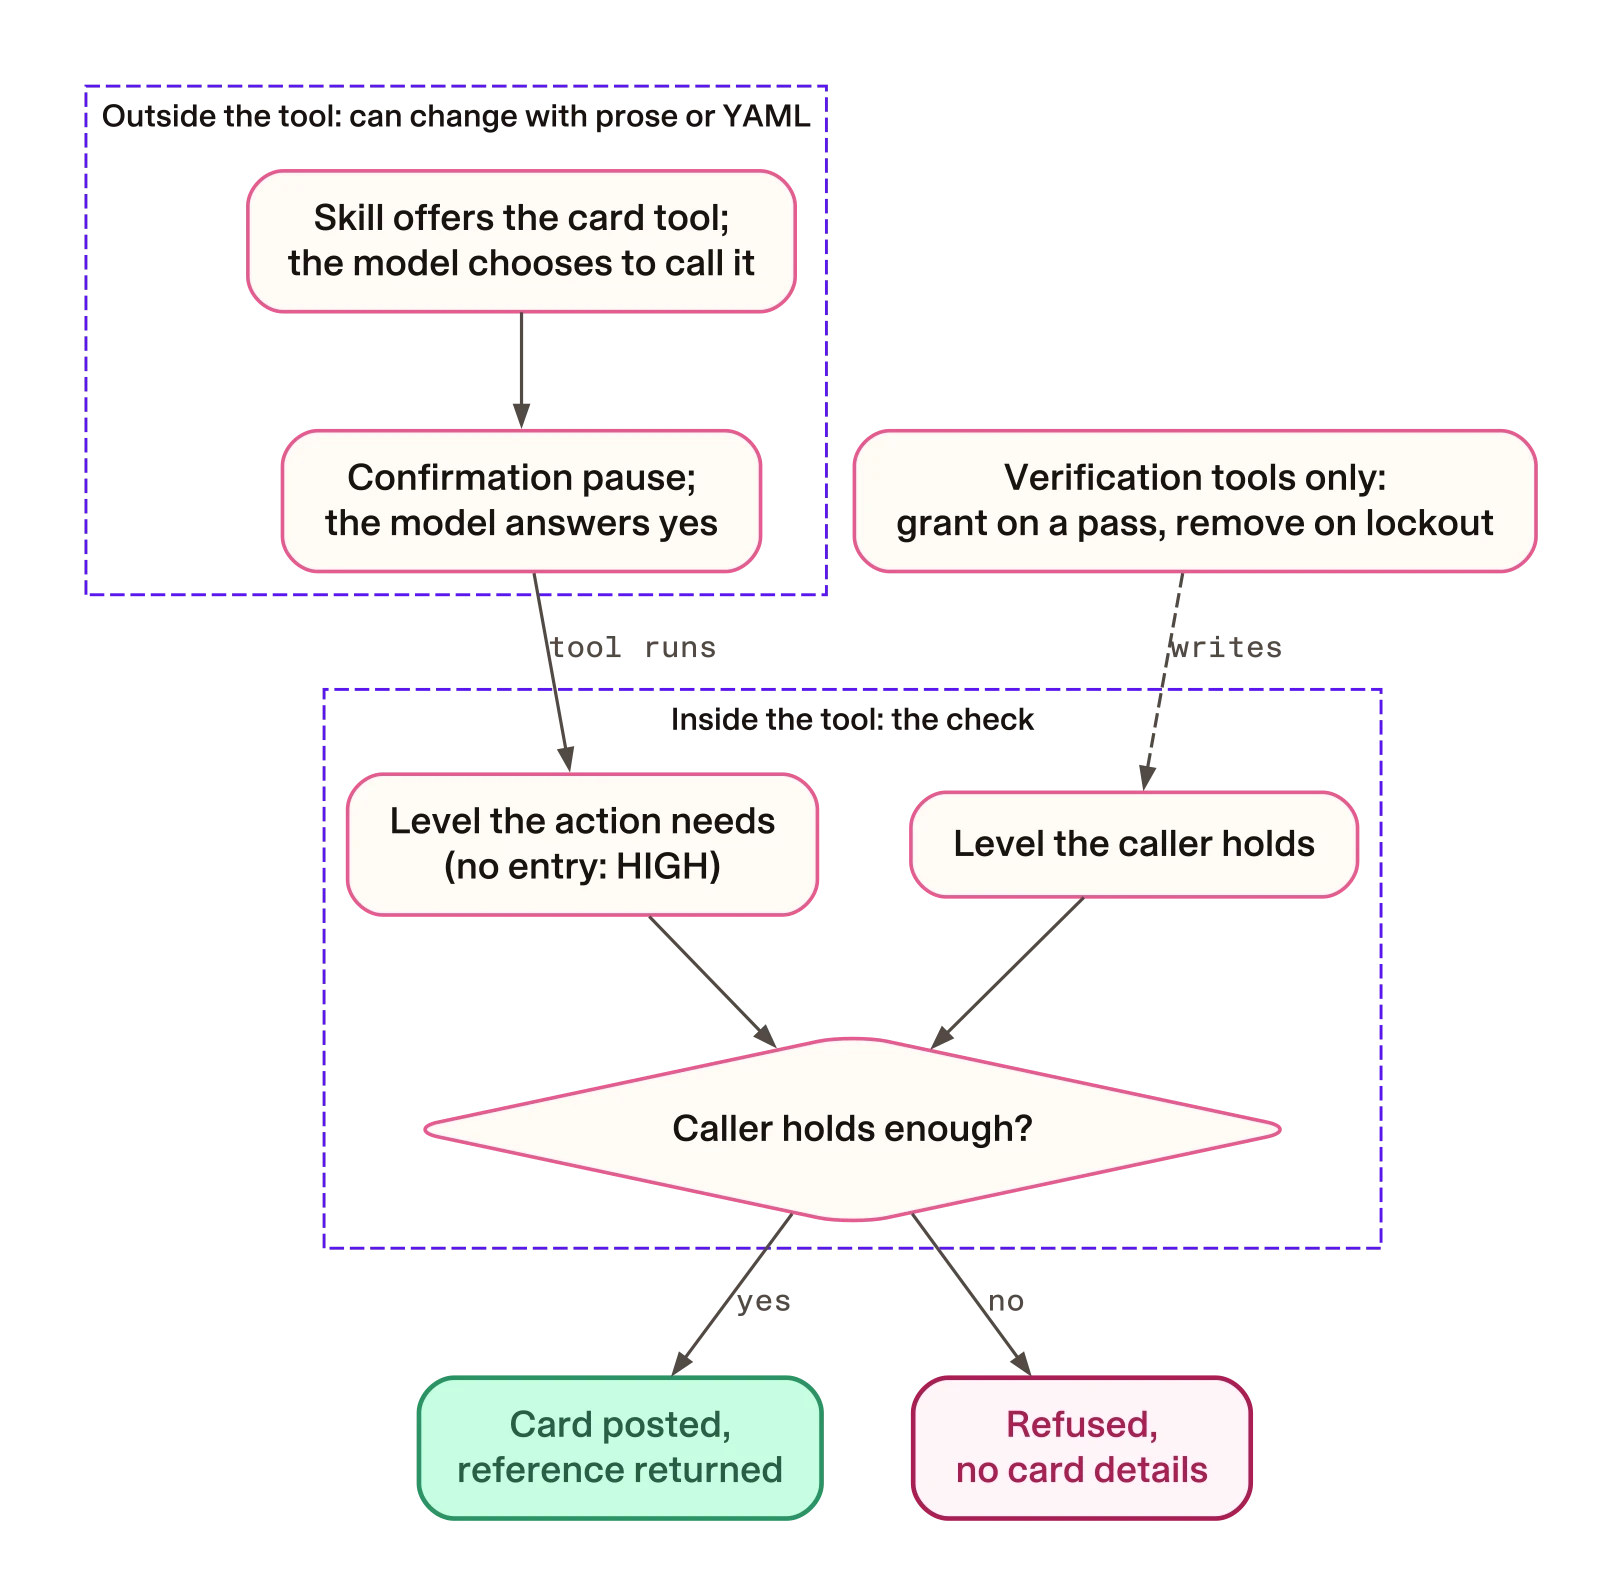
Everything in the top box can change when someone edits a skill or swaps the model. Only the verification tools write the level the caller holds, and the model cannot set it. So ask for evidence about the bottom box.
How to review each action
Work through your action register one row at a time. Each step says what to ask engineering for.
Set each risk level by what the action does
Give each action a level based on what happens if it succeeds. Do not base it on who is asking or how far into the call they are. The same caller, in the same call, can be cleared for a balance and not cleared for a new card.
Here is the register for the six actions in the pattern. The owners are example roles.
| Action | Risk level | Check in the tool? | Owner |
|---|---|---|---|
get_store_hours | LOW | No, by design: public information | Branch network owner |
get_fee_schedule | LOW | No, by design: public information | Pricing owner |
get_balance | MEDIUM | Yes, first statement after the docstring | Accounts owner |
get_recent_bill | MEDIUM | Yes, first statement after the docstring | Billing owner |
reissue_card | HIGH | Yes, first statement after the docstring | Card operations owner |
transfer_funds | HIGH | Yes, first statement after the docstring | Payments owner |
| Any action with no row | HIGH, by default | Only if the tool calls the check | Owner of the risk table |
The last row matters most. Someone adds a new action, such as
close_account, and forgets to give it a level. Ask what happens then. In the
pattern, the lookup falls back to the strictest level. This excerpt is the
last two lines of tier_for in authpolicy/actions.py:
    policy = POLICIES.get(action)
    return policy.tier if policy is not None else AuthTier.HIGH
A test, test_unknown_action_defaults_to_high, checks that an unlisted action
comes back as HIGH. Another test calls the check with no call details at all
and confirms it refuses.
Ask for a direct test of each tool
A direct test calls the tool itself, as the code would, with a caller at a
lower level. It does not go through the model. This excerpt from
tests/test_guard.py calls the card tool as a caller who holds a correct
passphrase, so MEDIUM:
        context = caller_at(AuthTier.MEDIUM)
        result = payload(
            run(reissue_card(delivery_address="12 Elsewhere Street", context=context))
        )

        self.assertFalse(result["ok"])
        self.assertTrue(result["step_up_required"])
        self.assertEqual(result["required_tier"], "high")
        self.assertEqual(result["held_tier"], "medium")
        # The action did not happen. These keys exist only on success.
        self.assertNotIn("dispatched", result)
        self.assertNotIn("reference", result)
The test passes only if the tool refuses and returns no card reference. A second test reads every HIGH action from the risk table and runs the same check on each. A new HIGH action is covered the day someone adds it to the table.
Watch the test fail without the check
A test that passes proves little until you have seen it fail. Ask engineering
to remove the check and run the tests again. The pattern ships this as
make prove. We ran it offline; its output, with colour codes removed:
1. removing the tier guard from reissue_card…
2. running the eval suite without it…
   red, as it must be.
3. guard restored.
4. re-running to prove the restore was clean…

The guard is load-bearing:
  without it the suite fails; with it the suite passes.
With the card check removed by hand, seven of the 36 tests failed. That is the card row’s evidence.
Then we removed the check from the two MEDIUM tools, the balance and the bill. Nothing failed: that is the run shown at the top of this guide. The checks are in the code, but no test depends on them. The missing test is small: call each MEDIUM tool directly at a lower level and confirm it refuses with no balance or bill. The mutation-testing guide shows how to make this a habit.
Test the lockout on every path
A lockout is what happens when the caller runs out of attempts. In the pattern, a lockout removes the caller’s level and returns a result telling the model to stop and hand the call to a person. Its tests confirm that wrong answers lead to a lockout and that the card stays refused afterwards.
Those tests send only wrong answers. None sends a correct answer after a lockout. So we wrote two short offline probes of our own. They are not part of the pattern’s tests. Each one runs the pattern’s real verification and banking tools with a test caller:
After a code lockout
This probe sends two wrong codes and tries the card and the balance. Then it sends the correct passphrase and tries both again. Its output, unedited:
otp: retry | auth_tier = medium | locked_out = None
otp: locked_out | auth_tier = none | locked_out = True
reissue_card ok: False
get_balance ok: False
passphrase: passed | auth_tier = medium | locked_out = True
get_balance ok: True
reissue_card ok: False
After a passphrase lockout
This probe sends six wrong passphrases, then the correct one, then asks for the balance. Its output, trimmed to these steps:
wrong passphrase 1: retry | auth_tier = none | locked_out = None
wrong passphrase 2: locked_out | auth_tier = none | locked_out = True
wrong passphrase 3: locked_out | auth_tier = none | locked_out = True
wrong passphrase 4: locked_out | auth_tier = none | locked_out = True
wrong passphrase 5: locked_out | auth_tier = none | locked_out = True
wrong passphrase 6: locked_out | auth_tier = none | locked_out = True
correct passphrase: passed | auth_tier = medium | locked_out = True
get_balance ok: True
The card stays refused, so the HIGH check holds. But after either lockout, a correct passphrase brings MEDIUM back, and the balance is shown again. The passphrase tool does not look at the lockout flag. From reading that tool and the skill files, what stands in the way in a live call is instructions to the model, not a check in code. We did not test a live call.
The pattern also states one limit itself. Its attempt count is kept for one call only, so a caller who hangs up and calls again starts fresh.
Ask for two things here. First, a lockout test that goes through the real tool, then sends the correct answer on every path that can grant a level. Second, ask where the lockout is stored, because a lockout kept in one call’s memory ends when the call does.
Check what a refusal and the logs carry
On a voice channel the caller says the secret out loud. The pattern’s code
says every secret passes through one function, redact, which returns only
its length. A test confirms that it never returns the secret.
Another test checks that the card tool’s refusal holds no secret. But that refusal is built only from the action name, the risk levels and fixed text, so the test cannot fail. The passphrase and code tools, which do receive the spoken secret, have no such test. Ask for one on each, for a pass, a retry and a lockout.
Record a decision for each action
The permissions guide lists the fields of a sign-off. With the evidence above, each field can point at something an engineer can rerun. Here is an example record for two rows:
| Field | reissue_card (send a new card) | get_balance (tell the caller their balance) |
|---|---|---|
| Allowed | Post a card to a caller at HIGH | Tell one balance to a caller at MEDIUM or above |
| Access from | One-time code; the pattern warns a code read aloud is closer to a second secret than proof of the phone | Correct passphrase |
| Evidence | Direct tests at lower levels; make prove red then green; seven tests fail with the check removed | None that depends on the check: with it removed, every test passes |
| Open gaps | No secret test on the verification tools; attempt count resets on a new call | No direct test; a correct passphrase brings access back after a lockout; attempt count resets on a new call |
| Decision | Approve at HIGH, with the secret tests due before the next release | Hold until the check has a direct test and the lockout holds for a correct passphrase |
| Owner | Card operations owner | Accounts owner |
| Review again | At the next change to the card tool or the risk table | At the next change to the account or verification tools |
How to check the evidence yourself
Ask engineering to run the pattern’s unit tests at the exact revision you are approving, and to send you the output. For this guide’s example, these commands get the pattern at the revision we tested:
git clone https://github.com/RasaHQ/rasa-community-resources.git
cd rasa-community-resources
git checkout 69e27b6a50c4700f95f2c13d4609d0a3f8cba7d2
cd patterns/voice-auth-stepup
You need uv, the Python package manager. The next command uses it to install
the Rasa version the pattern pins in pyproject.toml, then runs the unit
tests. These tests need no model and no API keys.
- Any system
make test
When we ran this in a fresh copy, it created the environment, installed the pinned Rasa version and printed Ran 36 tests and OK. Then run the
check-removal test:
- Any system
make prove
It should print the red-then-green output shown above. It removes the card check, runs the tests, and puts the check back.
For your own agent, ask for the same three things: the full test output, the output with each check removed, and the revision both came from.
Trade-offs
A strict default adds friction. An action nobody classified needs HIGH, so it is refused for any caller below HIGH. That is safe, but callers get asked for a stronger check until someone adds the row. Someone has to own that delay.
The evidence costs engineering time. Each risky row needs a direct test, a run with the check removed, and a rerun at each release. Some rows will stay on hold, as the balance row does above.
Limits
- Every test and probe in this guide ran offline against the code. None is a live call, and none shows how a model behaves in a call.
- We did not run the pattern’s conversation tests. They need a trained model and API keys.
- Northgate Bank is fictional, and the risk levels are the pattern’s teaching choices.
- This is an engineering review aid, not a legal or compliance ruling.