Guide · Evaluation / data specialist
How to mutation test an AI agent guard in Python
Break your AI agent's guard on purpose, one small edit at a time, and check that your tests fail for every edit you make.
Key takeaways (3)
- A suite that catches every break it makes itself has only tested the breaks its author thought of.
- Aim your own breaks at the checks that decide whether an earlier result still stands.
- Report each kind of break on its own line, with how many you tried and which survived.
Your agent has a guard that decides whether a request may finish. When the request waits for someone else, the rules can change before it resumes. You need tests that catch an old request being completed under rules it never passed.
This guide uses a fictional handoff waiting for a desk’s acknowledgement. We
removed rules from the hash saved with the request. The existing seven tests
still passed, yet the changed guard accepted a pending request after its
acknowledgement rule was removed. You will reproduce the gap and write a
test that catches it.
We checked this on the
casebook lab
in RasaHQ/rasa-community-resources. Its offline suite has seven tests. One
of them removes each rule from each of 62 synthetic cases and checks that the
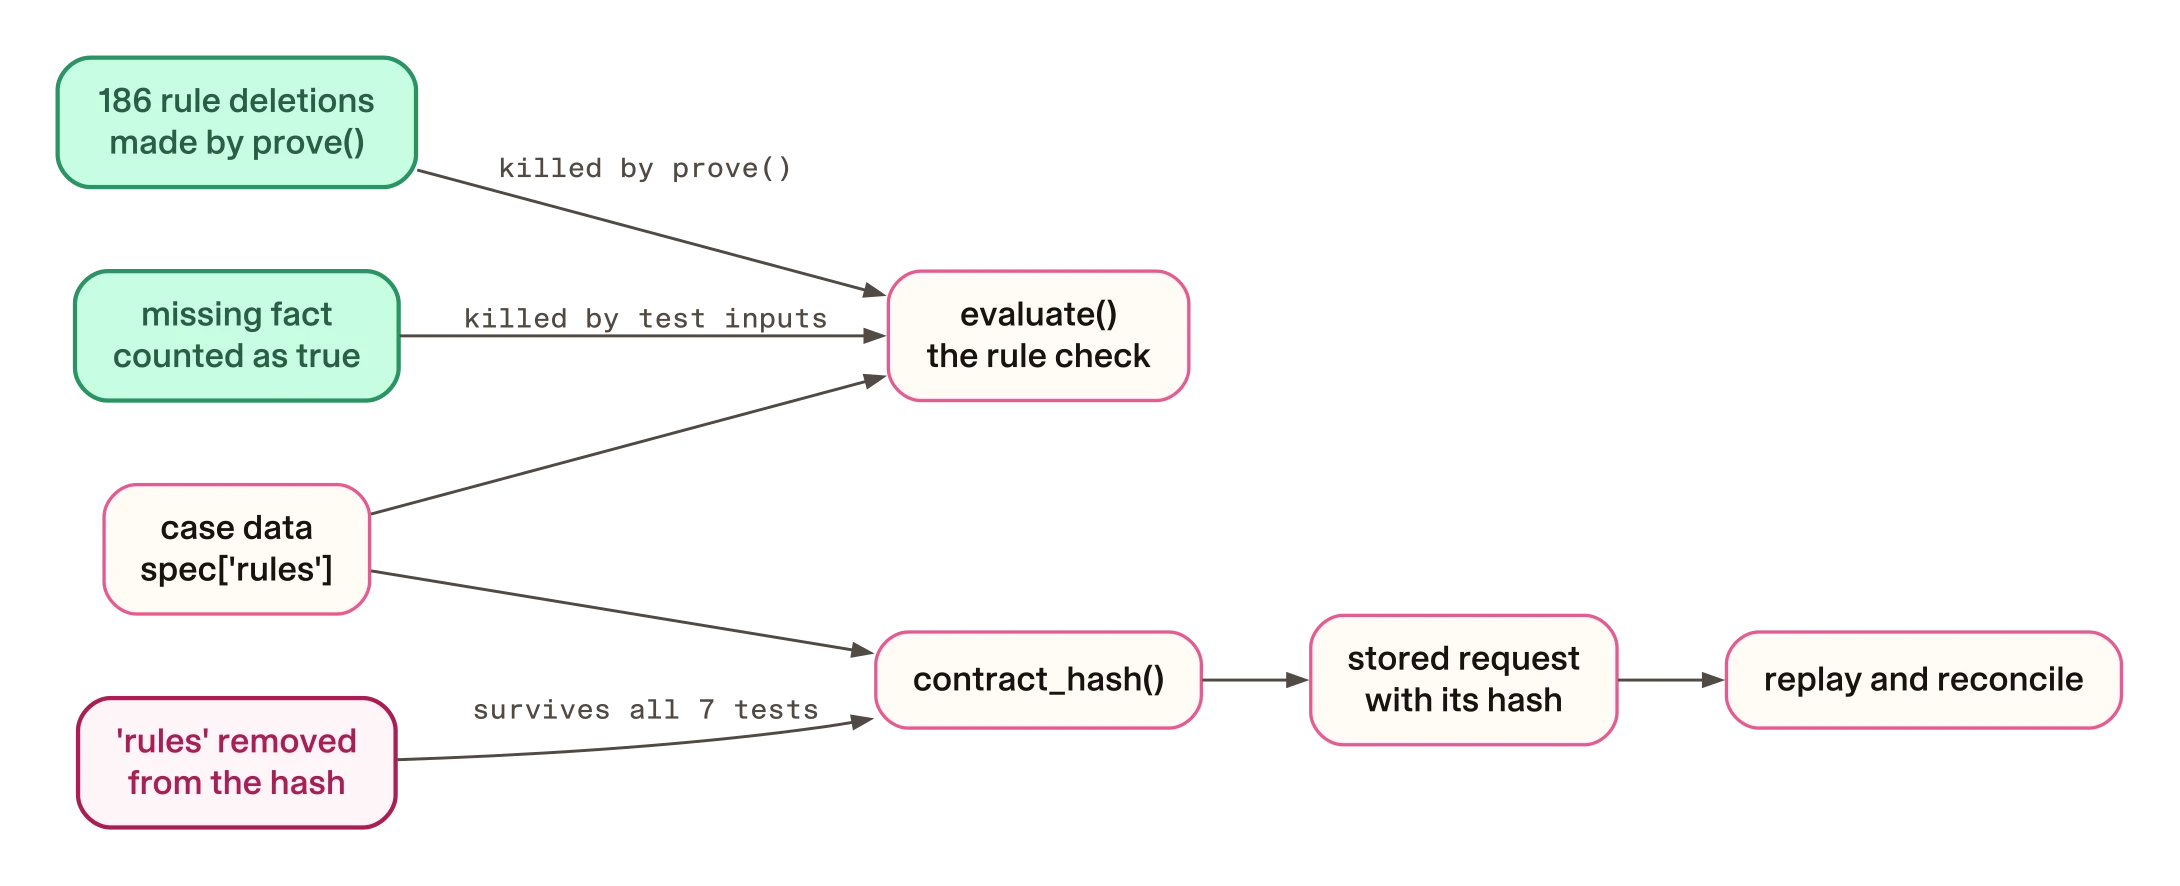
guard notices. That is 186 deliberate breaks, all caught. Then we deleted one
word from the guard’s own code. This is the change, as an excerpt of the diff:
 def contract_hash(spec: dict) -> str:
-    return digest({k: spec.get(k) for k in ('slug', 'action', 'rules', 'receipt', 'provenance', 'intakeKind')})
+    return digest({k: spec.get(k) for k in ('slug', 'action', 'receipt', 'provenance', 'intakeKind')})
We ran the same seven tests again, at 4aa0c44, the commit this site pins.
This is the end of that run, trimmed: the six other test lines, which also
say ok, are left out.
test_all_authored_oracles_and_mutations (tests.test_casebook.CasebookTests.test_all_authored_oracles_and_mutations) ... ok

----------------------------------------------------------------------
Ran 7 tests in 1.620s

OK
With that word gone, the guard can mark an old request as done after the rules it was waiting on have been deleted. Every test stays green, including the one that reports 186 breaks caught. On the original file, coverage reports that line as run. When we ran mutmut, a mutation testing tool, on the same file, it found this gap only as 2 of 299 survivors.
Breaking code on purpose to see whether a test fails is called mutation testing. The lab’s own code uses its words. Each changed copy is a mutant. A mutant the tests catch is recorded as killed. One that gets through is a survivor: behaviour that no test pins down.
The fix is to write your own mutants, aimed at the checks that decide whether an earlier result still stands. That matters if your agent retries requests or finishes them later, because those are the checks that let an old result through. If your own code ties an old result to the current rules with an idempotency key, a cache key or an ETag, aim mutants there too. Keep a new test only if it fails on the mutant.
What you need: Git and Python 3. The lab’s tests use only Python’s
standard library, so they need no Rasa install, model, licence or network. We
reran the clean suite, this mutant and the new test at 4aa0c44, the commit
this site pins, with the same results. mutmut ran there only.
Limits says which commit each other check used.
Why the built-in mutation check misses it
The lab makes its own mutants in prove(), in casebook.py. This excerpt is
the loop, at its source indentation:
    # Exercise each broken predicate against the independently stored oracle.
    killed = []
    for rule in spec['rules']:
        mutant = json.loads(json.dumps(spec))
        mutant['rules'] = [r for r in mutant['rules'] if r['field'] != rule['field']]
        fixture = next(f for f in spec['variants'] if f['name'] == rule['field'] + '-false')
        # Mutant no longer considers the deleted predicate part of the contract.
        facts = {k: v for k, v in fixture['facts'].items() if k != rule['field']}
        with tempfile.TemporaryDirectory() as tmp:
            outcome = execute(mutant, facts, 'mutant', Path(tmp) / 'ledger.sqlite')
        assert outcome['status'] != fixture['expected']['status'], 'surviving predicate deletion'
        killed.append(rule['field'])
Read it for three things:
- What it changes: One rule, removed from the case data. Every case has three rules, so every case gives three mutants.
- Where it runs: Once, on an empty ledger: the small SQLite database where the guard records each request it commits.
- What counts as killed: The mutant’s result differs from the result the stored test input expects.
The suite is strong where it looks. We changed the rule check in evaluate()
so that a missing fact counted as true. The suite failed at once, with one
failure in each of the 62 cases. Every case carries test inputs where each
fact is false, missing or a string instead of True, and those caught it.
What contract_hash decides
When the guard commits a request, it stores a hash of the case beside it.
This is the whole function from casebook.py:
def contract_hash(spec: dict) -> str:
    return digest({k: spec.get(k) for k in ('slug', 'action', 'rules', 'receipt', 'provenance', 'intakeKind')})
The hash covers six parts of the case, including its rules. When the same request ID comes back later, two checks compare the stored hash with the case as it is now:
- Replay, in
execute(), returns the stored result if nothing has changed. - Reconcile, in
reconcile(), finishes a request that was leftpendingwhile it waited for a receipt.
This excerpt is the reconcile check, at its source indentation:
        if row['case_id'] != spec['slug'] or row['contract_hash'] != contract_hash(spec):
            return result('conflict', 'receipt_contract_changed', effects=1)
Replay also compares a second hash, the fingerprint, which covers the facts
checked before the request ran. Reconcile does not. So once 'rules' leaves
the hash, reconcile misses every rule deletion, and replay misses some.
Why does no test notice? Only one test changes a case and then comes back
with a request ID that is already stored. It changes the case’s
provenance.revision and nothing else. The hash covers six fields, and the
tests check one of them directly.
Reading tools/cases.py, the lab’s Rasa tool reuses the request ID when a
case is rehearsed again, so it meets this check (we did not run the tool).
How to mutation test your own guard
This extends a habit from the fixture guide and the action register guide: delete one key or guard line and check that a test fails.
Make a throwaway copy
These commands clone the companion and add a second working copy at the pinned commit, in a folder next to your clone. In your own project, use your repository and commit instead.
git clone https://github.com/RasaHQ/rasa-community-resources.git
cd rasa-community-resources
git worktree add ../casebook-scratch 4aa0c44
cd ../casebook-scratch/tutorials/rasa-ai-team-casebook
When you are done, git worktree remove ../casebook-scratch, run from your
clone, deletes the copy.
Run the suite on the clean code
Run the tests once before you change anything. This is the lab’s own
make proof target:
- macOS
python3 -m unittest discover -s tests -v- Linux
python3 -m unittest discover -s tests -v- Windows
python -m unittest discover -s tests -v
All seven tests should print ok, then OK.
Find the checks that compare old and new
Search your guard for places where a value saved earlier is compared with one worked out now. Stored hashes, request fingerprints and cached results are typical.
Make one small edit and rerun
Each version below copies the original file and removes 'rules', from
line 97. It then shows the change, runs the suite and puts the original
back. It edits casebook.py in place, so run it only in the throwaway copy.
macOS
cp casebook.py casebook.py.orig
sed -i '' "97s/'rules', //" casebook.py
diff casebook.py.orig casebook.py
python3 -m unittest discover -s tests -v
cp casebook.py.orig casebook.py
Linux (GNU sed)
cp casebook.py casebook.py.orig
sed -i "97s/'rules', //" casebook.py
diff casebook.py.orig casebook.py
python3 -m unittest discover -s tests -v
cp casebook.py.orig casebook.py
Windows (PowerShell)
Copy-Item casebook.py casebook.py.orig
$lines = Get-Content casebook.py
$lines[96] = $lines[96].Replace("'rules', ", "")
Set-Content casebook.py $lines
Compare-Object (Get-Content casebook.py.orig) (Get-Content casebook.py)
python -m unittest discover -s tests -v
Copy-Item casebook.py.orig casebook.py -Force
The diff or Compare-Object line shows that the edit landed. If it prints
nothing, the edit missed and the suite is testing the original file.
PowerShell counts lines from zero, so line 97 is $lines[96].
Write a test that kills the mutant
If the suite stays green, write the test it is missing.
Try it first, then compare with our test
Commit a request that stops at pending. Delete the receipt rule it is
waiting on, then try to reconcile under the changed case. The original guard
should refuse with conflict. This is our scratch test, which is not part of
the companion:
import json
from pathlib import Path
import tempfile
import unittest
from casebook import execute, load_case, reconcile


class ContractBindingTests(unittest.TestCase):
    def test_changed_rules_cannot_reconcile_a_committed_request(self):
        spec = load_case('contextual-handoff')
        with tempfile.TemporaryDirectory() as tmp:
            database = Path(tmp) / 'ledger.sqlite'
            facts = dict(spec['facts'], desk_acknowledged=False)
            self.assertEqual(execute(spec, facts, 'r1', database)['status'], 'pending')
            changed = json.loads(json.dumps(spec))
            changed['rules'] = [r for r in changed['rules'] if r['field'] != 'desk_acknowledged']
            later = {k: v for k, v in spec['facts'].items() if k != 'desk_acknowledged'}
            self.assertEqual(reconcile(changed, later, 'r1', database)['status'], 'conflict')
Run the new test on both versions
Save the test as tests/test_contract_binding.py in the lab folder. The edit
step put the original file back, so run the test, apply the edit again, and
rerun. On macOS:
python3 -m unittest tests.test_contract_binding -v
sed -i '' "97s/'rules', //" casebook.py
python3 -m unittest tests.test_contract_binding -v
cp casebook.py.orig casebook.py
On Linux, drop the '' after sed -i. On Windows, use the edit lines from
the PowerShell tab. Keep the test only if the mutant turns it red.
How to check the fix works
On the original casebook.py, the new test passes. On the mutant, it fails.
These are the last lines of the mutant run at the pinned commit, trimmed: the
FAIL test line, the FAIL: banner and the traceback above them are left
out.
AssertionError: 'succeeded' != 'conflict'
- succeeded
+ conflict


----------------------------------------------------------------------
Ran 1 test in 0.004s

FAILED (failures=1)
Read what the mutant did. A handoff was waiting for the desk to acknowledge
it. Someone deleted the acknowledgement rule from the case. Reconcile then
marked the old request succeeded against a check it never passed. The
request did not change. The rules it was judged by did.
This guide recommends keeping the commit-and-reconcile test. It checks what
the hash exists for: a changed case cannot finish an old request. A direct
check of the hash also tells the two versions apart: deleting one rule changes
contract_hash on the original file and not on the mutant. It is shorter and
needs no ledger, but it cannot see whether reconcile still compares the hash. The cost of the
recommended test is setup: a ledger, a committed request and a changed copy
of the case.
Count what you tried, not only what you killed
Once one field in the hash survives, try the others. We deleted each of the six fields from the hash in turn, one per run, and reran the seven tests:
| Field removed from the hash | Seven-test suite | What it means |
|---|---|---|
provenance | 1 failure | Killed by the one test that edits a committed case |
slug | OK | Equivalent: the case name is still checked directly |
rules | OK | Survivor: rule changes go unnoticed at reconcile |
action | OK | Survivor |
receipt | OK | Survivor |
intakeKind | OK | Survivor |
The slug row needs a person to read the code. The case name is already in
the fingerprint, and reconcile checks it on its own. So removing it from the
hash changes nothing a caller could see. We call this an equivalent
mutant: here it makes no difference, so no test should be written to kill
it. We had to read the code to tell it apart from a real gap.
The other three survivors are text fields that describe the case. Whether a change to one of them should cancel a committed request is a decision for the lab’s owner. The code includes them in the hash today.
An honest report of this suite gives one row per kind of edit:
| Kind of edit | Tried | Killed | Equivalent | Survived |
|---|---|---|---|---|
Rule deleted, made by prove() | 186 | 186 | 0 | 0 |
| Missing fact counted as true | 1 | 1 | 0 | 0 |
| One field deleted from the hash | 6 | 1 | 1 | 4 |
The evaluation set guide asks the same of agent evaluations: report passed, failed and not-run counts for every slice.
Trade-offs
The survivor is narrower than it looks. Most rules in the lab are checked before the request runs (155 of 186), so deleting one changes the fingerprint and replay refuses anyway. Reconcile has no such backstop. But every case carries a revision, and the one test that edits a committed case changes exactly that. If everyone who edits a case’s rules also bumps its revision, the guard catches the change. The mutant shows that the rules are not tested, not that the lab is unsafe as used.
The cost is time and judgement. Every survivor, whether you wrote the mutant or a tool generated it, has to be read and sorted into a gap or an equivalent.
We ran mutmut 3.8.0 on casebook.py at the pinned commit:
mutmut run on casebook.py | Mutants | Killed | Survived | No test reaches it |
|---|---|---|---|---|
| With the lab’s seven tests | 1,113 | 661 | 299 | 153 |
| With our new test added | 1,113 | 663 | 297 | 153 |
mutmut made 15 mutants of contract_hash. None deletes a field from the
tuple. Thirteen rename one of the six field names, and two replace what is
hashed with None. This is one of the renames, from mutmut show, trimmed to
the changed lines. The status header (from the run with our new test), the
--- and +++ lines and the @@ hunk header are left out.
 def contract_hash(spec: dict) -> str:
-    return digest({k: spec.get(k) for k in ('slug', 'action', 'rules', 'receipt', 'provenance', 'intakeKind')})
+    return digest({k: spec.get(k) for k in ('slug', 'action', 'XXrulesXX', 'receipt', 'provenance', 'intakeKind')})
The case has no key called XXrulesXX, so the rules drop out of the hash
just as with our deletion. All 153 untested mutants are in the lab’s
command-line main(). With the lab’s tests, 11 of the 15 survived. Sorted by
hand, they match our six-field sweep:
contract_hash survivors, lab’s tests only | Count | Sorted as |
|---|---|---|
Rename 'rules' | 2 | The gap; our new test kills both |
Rename 'action', 'receipt' or 'intakeKind' | 7 | The other three survivors from our sweep |
Rename 'slug' | 2 | Equivalent, like deleting slug |
So the tool did find this gap, but as 2 of 299 survivors to sort. This guide recommends aiming a few mutants by hand at the stored-versus-current checks first. Then run a tool when you have time to sort what it finds.
Limits
- Every check here is an offline Python run against synthetic cases. None involves a model, a live conversation or a real service.
- We ran every check except mutmut at commit
69e27b6, with Python 3.14.3 on macOS. At the pinned commit4aa0c44, with Python 3.14.6, we reran the clean suite, the'rules'mutant, the new test and the throwaway copy, and ran mutmut there only. The lab’s code is identical at both commits. - These were not repeated at
4aa0c44: the missing-fact mutant, the six-field sweep and count table, and the replay test in the warn callout. Nor were the directcontract_hashcheck, the coverage reading and the three platform edits. - The throwaway-copy steps used a local clone. We did not run the
git clonecommand against GitHub. - The three platform edits ran on macOS only, the PowerShell one under PowerShell 7; we did not run the Windows commands on Windows.
- The counts are results from one lab, not rates.