Guide · AI product manager
How to measure an AI agent handoff to a human
Test that each fact your human desk needs reaches the handoff on the agent’s own path, and measure handle time from real calls.
Key takeaways (3)
- A passing offline test shows which fixed desk questions a handoff answers, not that handle time fell.
- A check can report nothing left to ask while the handoff still drops a fact the desk needs.
- Measure repeat questions, handle time and satisfaction from real transferred calls, with an owner for each.
Your AI agent now hands callers to a human with a structured package: who the caller is, what they want, and what they already tried. The tests pass. Now the launch review wants a number. Did callers stop repeating themselves?
The sample agent used here passes all 41 of its offline tests. It also has a built-in check that lists the questions the human desk would still have to ask. On the sample’s card-dispute path, that list is empty. Yet the package never says which charge the caller disputed.
This is the output of the sample’s real dispute and handoff tools, run
offline on Rasa Pro 3.21.0.dev5. It is trimmed to four lines. The run header
and the raise_dispute error, memory keys written, transferred and
ASKING FOR lines are left out:
dispute_* keys in memory: ['disputed_txn_id', 'disputed_txn_label']
desk_still_needs_to_ask: []
hint: Context package delivered. Tell the caller the handoff id and that they will not need to repeat themselves. Do not read back any withheld field.
intent.details: {"account_id": "acc_checking", "account_label": "Everyday Checking", "card_last_four": "4821"}
The caller picked a charge, and the dispute step saved it under one name. The handoff looks for it under three other names, so it never arrives. The desk sees the account and the card, but not the charge.
Check your own agent for the same pattern: one step records a fact under one name, another collects it under a different name, and a check that only counts filled fields stays green.
The fix is to test that each fact your desk needs reaches the package on the agent’s own path. Then report the offline count as package coverage, not as fewer repeat questions or shorter calls. That matters if your launch review quotes a business number, or if your desk acts on what the package says.
Why a passing test does not prove callers stopped repeating
The pattern counts against a fixed list. Five questions a desk agent asks at
the start of a call are each mapped to the package field that answers them.
This is the map, an excerpt from handoffpkg/desk.py:
_QUESTION_RETIRED_BY: dict[str, str] = {
    "Can I take your name?": "identity.display_name",
    "Can you confirm your date of birth?": "identity.verified_tier",
    "Which account is this about?": "intent.details.account_id",
    "What are you calling about today?": "intent.goal",
    "Have you tried anything already?": "attempts",
}
A function called unanswered_questions returns the questions whose field
is empty. Because the list is the same for every handoff, you can compare
one handoff with the next, and the old design with the new one. A one-line
handoff reason leaves all five unanswered. The redesigned package, in the
sample’s test, leaves none.
That is a real result, but it is narrow. The check asks whether a field is
filled, not whether it is right. In the test, the caller’s name is the
placeholder value_for_display_name, and it still counts. The check also
cannot see any fact that is not on the list, such as the disputed charge.
The handoff tool returns a second count, questions_retired. It counts the
lines the agent’s skills logged as answered, so it has no fixed total. On
the dispute path it reads 4, while the fixed check reads five out of five.
Put the fixed check in your review, and leave the second count out.
Where the charge goes missing
In the sample, each skill is a folder under skills/ with its own
tools.py and skill.md. The dispute skill saves the chosen charge in memory as disputed_txn_label. The
handoff tool collects dispute_amount, dispute_merchant and
dispute_date, and no tool writes those.
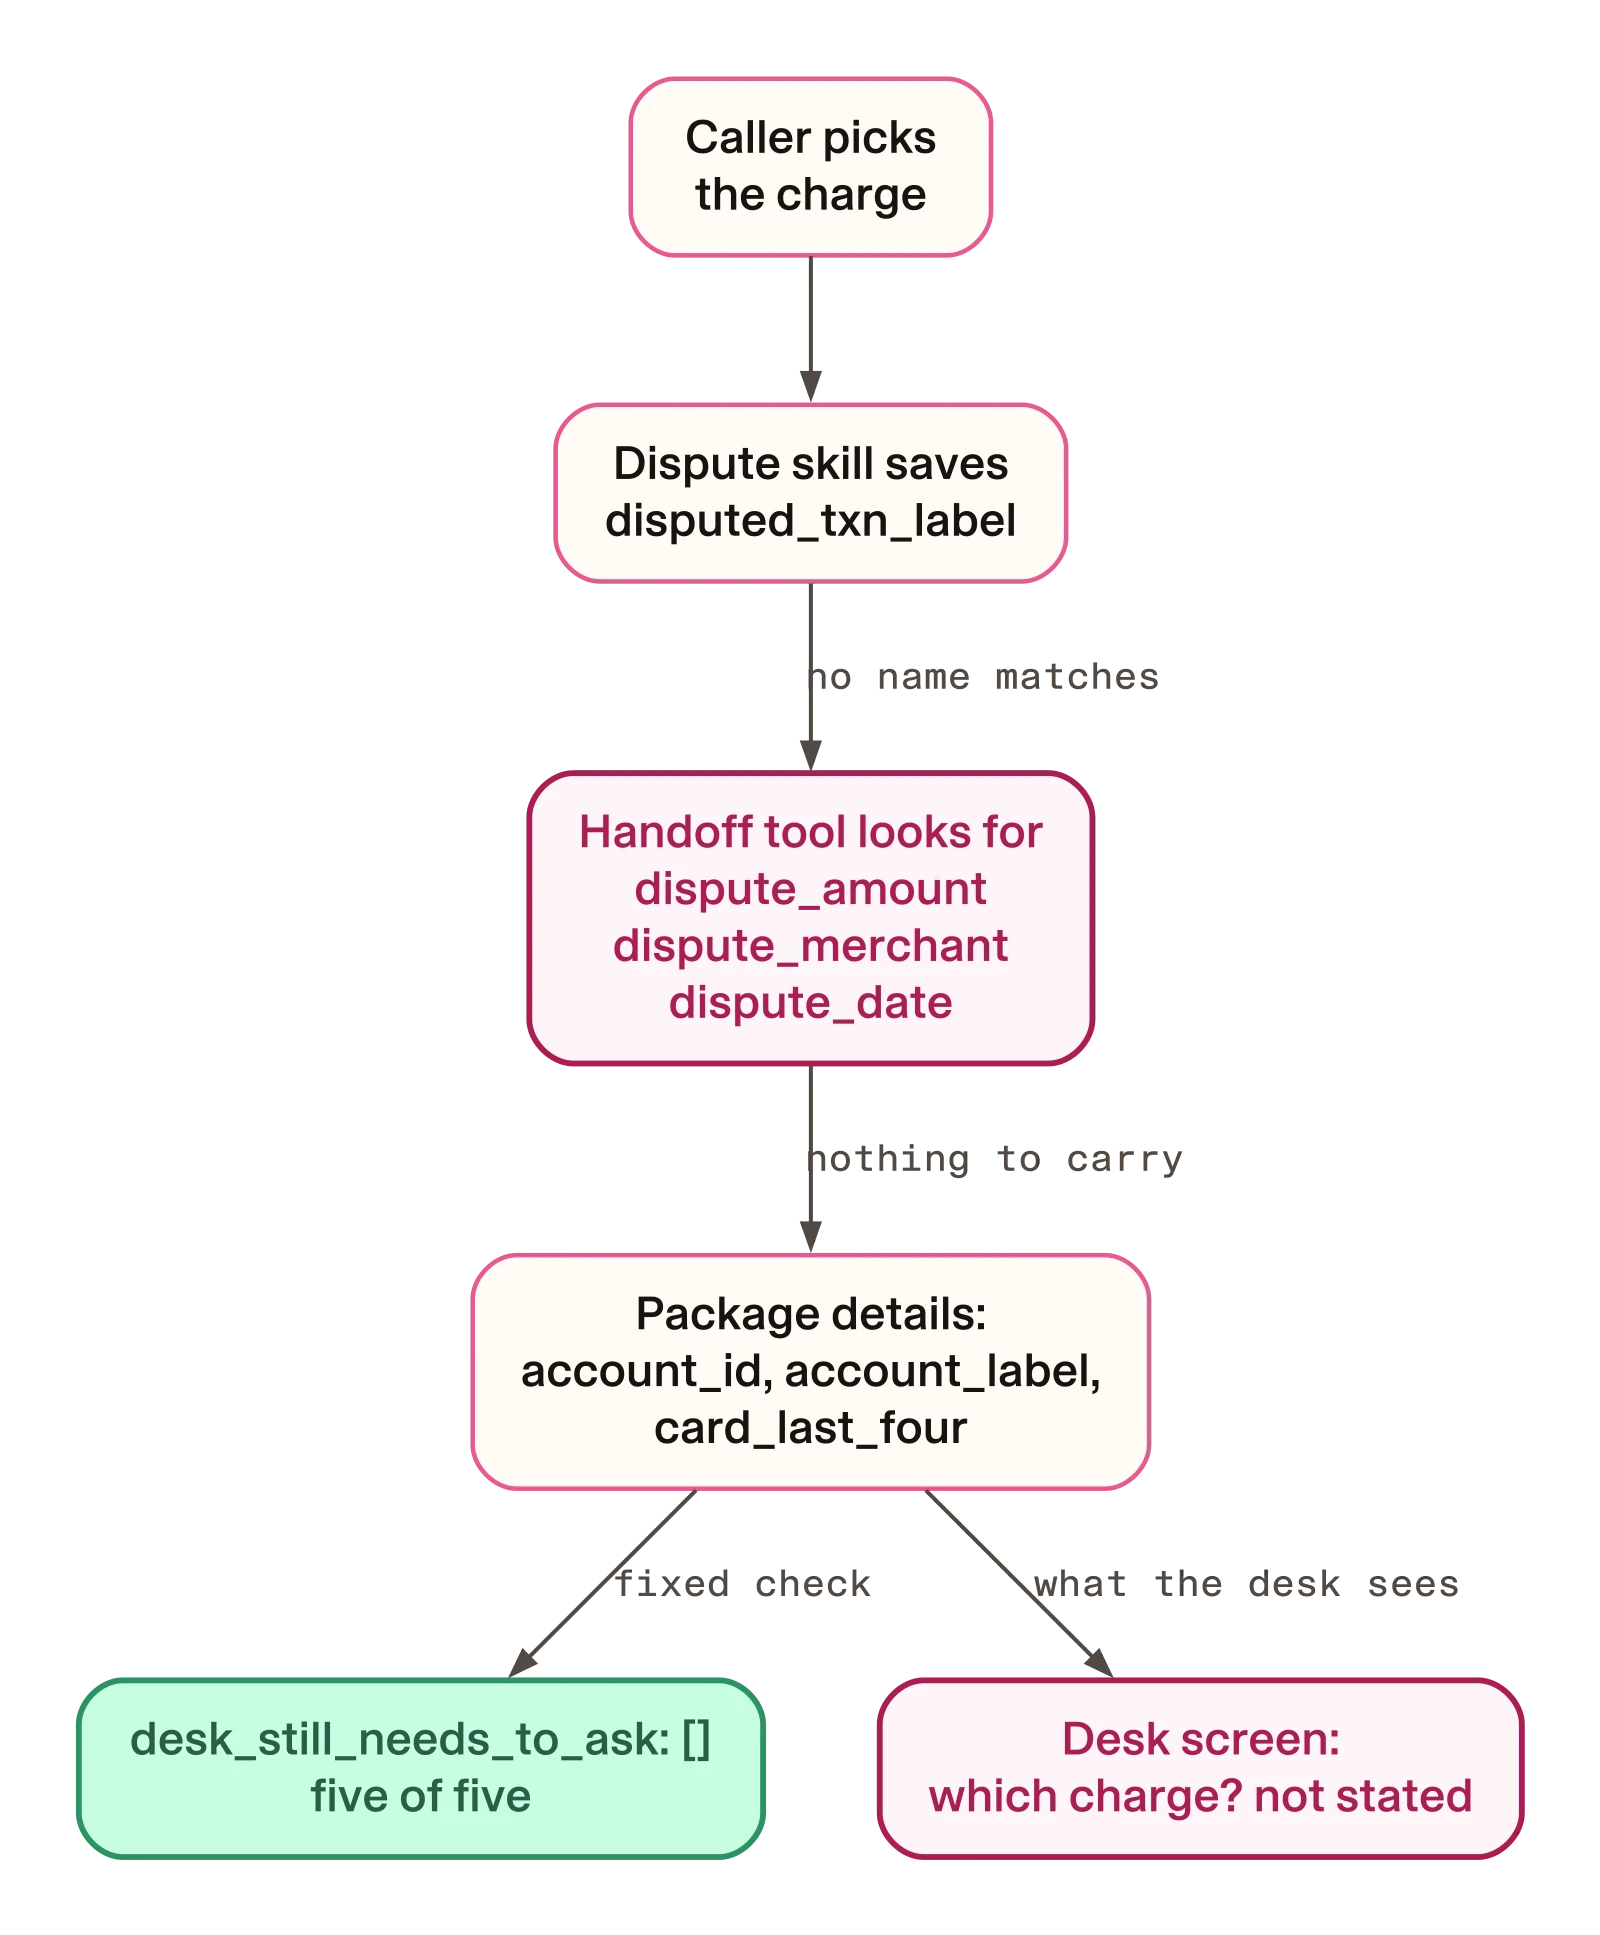
The sample’s test for this path checks three detail fields: the account id, the account name and the last four card digits. It does not check the charge, so the gap passes. We infer, without a test, that the desk would have to ask the caller which charge it was. The handoff summary guide reaches the same finding from the design side.
How to fix it
Work through these steps in your own project. The diffs below are excerpts
of the change we tested in a throwaway copy of the sample, saved as
fix.diff with this guide’s receipts.
Write down your desk’s opening questions
Take the questions from your desk’s call guide or QA scorecard, not from the sample. Give the list a version and a date. If the list changes, the count changes, even though no caller behaved differently.
If you add questions, add each one to both the list and the map. In the
sample, a question with no map entry raises a KeyError on every transfer.
A field the check does not recognise counts as unanswered on every handoff.
Make the test check every fact the desk needs
List the facts each case needs, not only the five opening questions. For a
dispute, that includes the charge. In the sample, extend the detail fields
in the agent-path test. This excerpt of fix.diff changes
tests/test_handoff_context.py:
-        for key in ("account_id", "account_label", "card_last_four"):
+        for key in ("account_id", "account_label", "card_last_four",
+                    "dispute_amount", "dispute_merchant", "dispute_date"):
Run make test before you fix the skill. The test should now fail. This is
our run, trimmed to one of the three failures. The verbose list of test
results, the traceback, the set of keys the skill writes, the two other
failures and the Ran 41 tests line are left out:
FAIL: test_the_agent_path_retires_every_desk_question (test_handoff_context.TestTheAgentPathSpecifically.test_the_agent_path_retires_every_desk_question) (key='dispute_amount')
AssertionError: 'dispute_amount' not found in {...} : no skill writes dispute_amount to memory
FAILED (failures=3)
Save the facts where the handoff looks for them
There are two ways to close the gap. You can make the dispute skill write
the three fields the handoff already collects. Or you can make the handoff
collect disputed_txn_label. This guide recommends the first. The sample’s
allowlist, the list of fields allowed to cross to the desk, already passes
the three fields into the package.
In the sample, the change goes in raise_dispute, next to the line that
saves the label. This excerpt of fix.diff changes
skills/dispute_transaction/tools.py:
     context.memory.set("disputed_txn_label", f"{charge['merchant']} {charge['amount']}")
+    context.memory.set("dispute_amount", charge["amount"])
+    context.memory.set("dispute_merchant", charge["merchant"])
+    context.memory.set("dispute_date", charge["date"])
The cost is that the amount, merchant and date now reach the desk. Check that your desk may see them. In your own project, make the same change in whichever tool records the case details.
A per-fact test is cheap, but someone has to add a line for each new fact. The sample’s handoff tool says the same of its own field list: a field added later is not collected until someone adds it. In this guide’s view, a single shared definition of the case fields, used by both the skill and the handoff, would remove the name mismatch. It costs a larger change and ties the two skills together. We did not build or test it.
Reword the promise to the caller
That last point comes from how the sample sets permissions. What the desk may
do depends on how far the caller was verified. The demo caller is at the
medium tier, and a dispute needs high. So the desk is told to
step the caller up before it can raise the dispute.
Change the hint in skills/human_handoff/tools.py and the closing step in
skills/human_handoff/skill.md. For example, say the specialist will see
the account and card details the agent passed on, and may need to confirm
the caller’s identity. Name only facts your test shows reach the package. We
did not test new wording with a model.
How to check the fix works
Run the tests from the pattern folder. They need only Python 3:
- Any system
make test
With both changes, all 41 tests passed in our run:
Ran 41 tests in 0.003s

OK
Then run the tool script below against the changed copy. The package
details now name the charge, and the check is still empty. This is the
output trimmed to two lines. The run header and the raise_dispute error,
memory keys written, dispute_* keys in memory, transferred, hint and
ASKING FOR lines are left out:
desk_still_needs_to_ask: []
intent.details: {"account_id": "acc_checking", "account_label": "Everyday Checking", "card_last_four": "4821", "dispute_amount": "$248.00", "dispute_date": "2026-08-29", "dispute_merchant": "Northgate Fuel"}
The script picks one charge, so this covers that charge only.
Show the tool script and how to run it
The script calls the dispute skill’s tools, then the handoff tool, with a
stand-in memory. It uses no model, network or licence. It needs Rasa Pro
importable, because the tool modules import rasa.mantle. In the pattern
folder, make install uses uv to create a .venv folder with the Rasa Pro
version the pattern pins. We ran the script with Rasa Pro 3.21.0.dev5 and
Python 3.12.
It writes a JSON file into fixtures/desk_queue, so run it in a throwaway
copy. Its docstring names an older commit and Rasa Pro 3.20.0rc1, where we
first ran it. It ran unchanged on 3.21.0.dev5. Save it as
agent_path_repro.py in the pattern folder, then run
.venv/bin/python agent_path_repro.py from that folder.
"""Drive the dispute path through the real tool functions, offline.

Run from a COPY of patterns/voice-handoff-context at 69e27b6 (transfer_to_human
writes a JSON file into fixtures/desk_queue). Needs rasa-pro 3.20.0rc1 importable
only because the tool modules import rasa.mantle; `@tool` returns the plain
function, so no model, network or licence is involved. The context below is a
stand-in exposing only `memory.get` and `memory.set`, which is all these tools use.
"""

import asyncio
import importlib.util
import json
import sys
from pathlib import Path

ROOT = Path.cwd()
sys.path.insert(0, str(ROOT))


def load(path, name):
    spec = importlib.util.spec_from_file_location(name, ROOT / path)
    module = importlib.util.module_from_spec(spec)
    spec.loader.exec_module(module)
    return module


class Memory(dict):
    def set(self, key, value):
        self[key] = value


class Context:
    def __init__(self):
        self.memory = Memory()


dispute = load("skills/dispute_transaction/tools.py", "dispute_tools")
handoff = load("skills/human_handoff/tools.py", "handoff_tools")


async def main():
    ctx = Context()
    await dispute.load_caller_context(context=ctx)
    await dispute.list_recent_charges(context=ctx)
    ctx.memory.set("disputed_txn_id", "txn_c101")  # the caller picks the first charge
    blocked = await dispute.raise_dispute(context=ctx)
    print("raise_dispute error:", blocked.llm_response["error"])
    ctx.memory.set("handoff_reason", "Dispute needs a second factor.")

    print("memory keys written:", sorted(ctx.memory))
    print("dispute_* keys in memory:",
          sorted(k for k in ctx.memory if k.startswith("dispute")))

    result = await handoff.transfer_to_human(context=ctx)
    r = result.llm_response
    print("transferred:", json.dumps(r["transferred"], sort_keys=True))
    print("desk_still_needs_to_ask:", r["desk_still_needs_to_ask"])
    print("hint:", r["hint"])

    queued = ROOT / "fixtures" / "desk_queue" / f"{r['handoff_id']}.json"
    package = json.loads(queued.read_text())
    print("intent.details:", json.dumps(package["intent"]["details"], sort_keys=True))
    print("ASKING FOR line:",
          next(l for l in r["_desk_preview"].splitlines() if l.startswith("ASKING FOR")))


asyncio.run(main())What to put in the launch review
Here is a review slide where someone in the room can check every line:
| Part of the slide | What it says | Evidence or owner |
|---|---|---|
| Proven offline | On the tested dispute path, the package answers all five opening questions. A one-line reason answers none. | The sample’s offline tests |
| Limits of the proof | Fields are filled, not checked for correctness. The test sets the tier, goal and attempts itself. | The agent-path test |
| Not yet measured | Handle time, repeat questions at the desk, questions not on the list, satisfaction with transfers | An owner, a data source and a date for each |
| Changes owed | Case facts written and tested on the agent’s path. Promise reworded. Question list versioned. | Engineering, conversation design and desk operations |
| Not on this slide | Redaction. The sample’s allowlist governs field names, cannot police free text, and is not a compliance control. | A separate review |
The rest comes from real calls, after launch:
- Store the coverage of each handoff. The sample’s tool computes the check on every transfer but does not store it. It does save each package to a file named after its handoff id, so you can recompute the check from those files.
- Sample transferred calls. Join each call to its package by handoff id. Count the listed questions the desk asked although the package answered them. Separately, list every question the desk asked that is not on the list.
- Report the figures side by side, with the sample size. Without the off-list questions, the fixed list hides a gap like the missing charge.
- Take handle time and satisfaction from their owners. Handle time comes from contact-centre reporting, on a comparable mix of calls. Satisfaction comes from your CSAT or complaints process, scoped to transfers.
Coverage is not a repeat rate. A desk agent may ask for a date of birth out of habit, even when the package answered it. Only call review shows that. How you count depends on what your contact centre records:
Calls are recorded, not transcribed
A QA reviewer lists the answered questions from each sampled package. They listen to the desk side of the call and mark each question as asked or not. They also note every other question the desk asked. The repeat rate is questions asked again over questions answered, in the sample.
Calls are transcribed
Search the desk agent’s turns for each answered question. Agents paraphrase, so a text match will miss “and your name is?” for “Can I take your name?”. Put questions that match nothing on the list aside for a reviewer to label. Have QA listen to a sample the search cleared, and report how many it missed.
Trade-offs
The step-up rule is correct design. A caller at the medium tier should not be
able to raise a dispute through the desk without a stronger check. But it
means a transferred dispute call still has work in it. A handle-time figure
for those calls would include that step, whatever the package carries.
The fixed list keeps figures comparable, but it only sees what is written into it. Keep the list of off-list questions next to it, so the gaps show.
Limits
- The sample is synthetic, with an invented caller, account and charges. No call was recorded and no desk agent was timed.
- Every run here is offline. The tool script calls the tool functions with a stand-in memory, not through a model, so a live conversation may take a different path.
- The tests run on plain Python 3 and do not use Rasa. We reran them at the companion revision the site pins, with the same result.
- We first ran the tool script with Rasa Pro 3.20.0rc1. We reran it on 3.21.0.dev5, the version the site pins, with the same output. Between the two revisions of the pattern, only its README, model settings and dependency pins changed.
- The fix was tested on one charge, in a throwaway copy. The reworded promise was not tested.
- The five questions are the sample author’s, written for a fixture desk.
Design a handoff a customer can trust covers consent, the context packet and recovery when the receiving team is unavailable. The tool and memory scope tutorial builds a bank agent that makes the caller verify exactly once.