Guide · Conversation designer / UX specialist
How to stop customers repeating themselves after a handoff
Build the human agent’s first screen from the fields your voice agent collected, and test the transfer promise against what your own tools send.
Key takeaways (3)
- Build the desk screen from the fields your agent collected, not from a summary paragraph written and stored separately.
- For each opening question the desk asks, name the field that answers it, and test with your agent’s real tools.
- Promise the caller only what those fields carry, and change the wording when the desk still has questions.
Your voice agent hands a caller to a person. Just before it does, it tells the caller they won’t need to repeat anything. Then the person on the desk has to ask for something the caller already gave.
We ran a sample agent’s own tools offline, on Rasa Pro 3.21.0.dev5, for a caller disputing a card charge. Two inputs were typed by hand: the charge the caller picked, and the reason line for the handoff.
Below is the desk screen’s line for what the caller wants, then one line of
the transfer tool’s report. We left out the attempts log, the
disputed_txn_label and dispute_date checks, the withheld fields, the
hint, the screen header and the rest of the screen.
ASKING FOR  Dispute a card transaction [account_id=acc_checking, account_label=Everyday Checking, card_last_four=4821] (stage: blocked)
desk_still_needs_to_ask: []
The account and the card crossed. The charge the caller disputed, Northgate Fuel $248.00, did not, although the dispute tool had stored it. The check for unanswered questions came back empty.
Separately, the tool’s hint tells the agent to promise no repeats, whatever the check says. This is the promise, from the sample’s responses file:
I’ll bring in a specialist and pass them everything we’ve covered, so you won’t need to repeat any of it. Shall I go ahead?
The guide to measuring a handoff tested a one-tool fix for this sample. With it, the same script’s screen line now carries the charge:
ASKING FOR Dispute a card transaction [account_id=acc_checking, account_label=Everyday Checking, card_last_four=4821, dispute_amount=$248.00, dispute_date=2026-08-29, dispute_merchant=Northgate Fuel] (stage: blocked)The fix, in short: build the desk’s screen from typed fields. Check on your agent’s own tool path that every fact the desk needs reaches them. Then promise only what those fields carry.
That matters if your agent promises callers they won’t repeat themselves. Any fact the desk needs that does not cross is something it has to ask for.
What you need: the sample pattern
patterns/voice-handoff-context
in RasaHQ/rasa-community-resources, plus Python. None of the runs here
needs a model, licence, key or network. The tool script also needs rasa-pro
installed. Versions are under Limits.
Why the desk asks again
The sample’s test desk opens with five questions: name, date of birth, which account, why you are calling, and what you have already tried.
A one-line reason answers none of them
The simplest handoff passes one line of text saying why a human is needed.
The pattern’s README says every handoff skill in its repository “captures
one free-text handoff_reason string and opens a ticket”.
The pattern’s make compare command builds the desk screen such a handoff
produces. This is the end of the first section of its output, the
one-line-reason screen. A second section, with the full demo screen, follows.
The caller will now be asked 5 question(s) they already answered:
  ✗ Can I take your name?
  ✗ Can you confirm your date of birth?
  ✗ Which account is this about?
  ✗ What are you calling about today?
  ✗ Have you tried anything already?
A sentence, however well written, gives the desk nothing it can tick a question off against.
A summary paragraph can drift from the facts
A summary paragraph sent with the data is a second copy that can go stale. The pattern’s authors give this design premise, not a measurement:
The human agent reads the prose — it is faster — so the human agent reads the stale one.
A fact saved under the wrong name never arrives
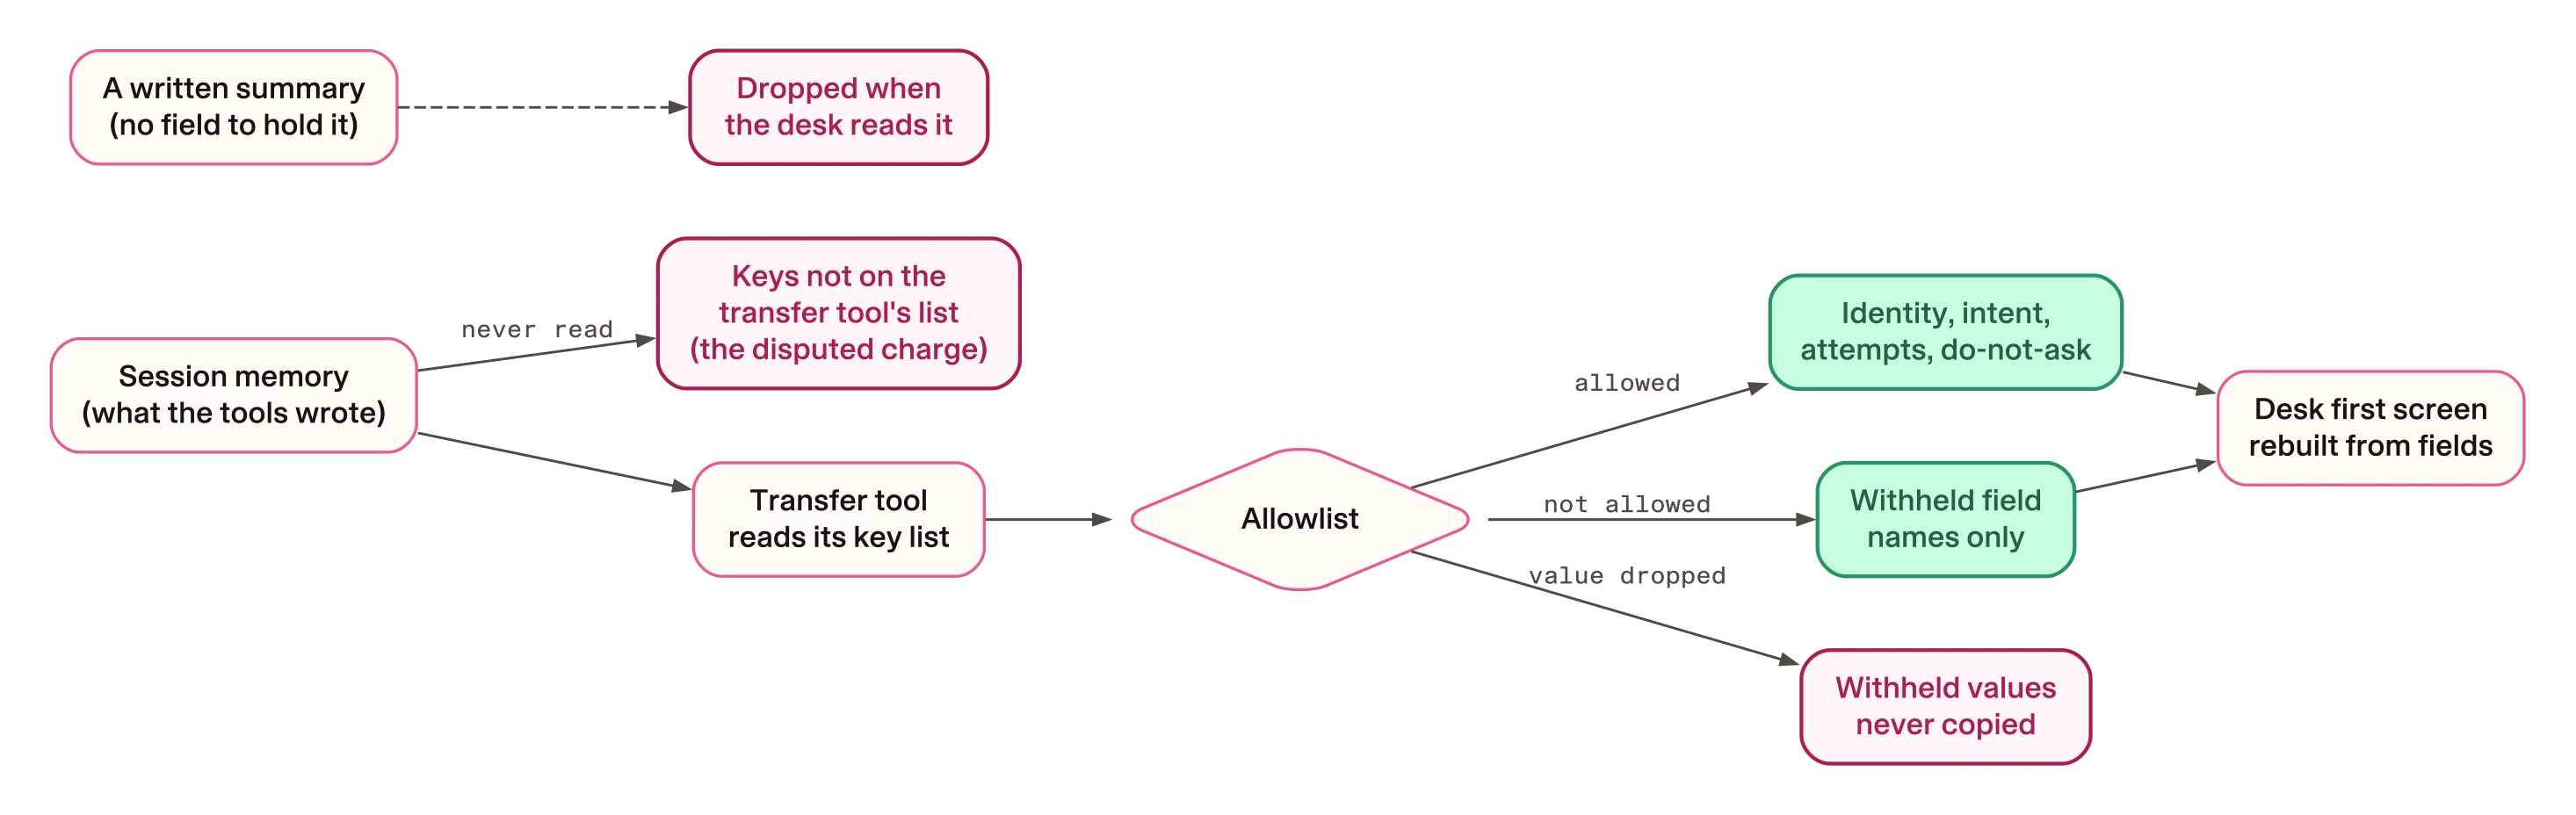
Fields avoid the drift, but only for the fields that are collected. In the sample, the dispute tool saves the chosen charge as one label. The transfer tool reads a fixed list of keys from memory, and the label is not on it.
That list names three other dispute keys, for the amount, merchant and date. No tool in the sample writes them, so the charge stays behind.
The check still passes because “Which charge is it?” is not one of the five questions. The check is only as wide as its question list.
How to fix it
In your own project, the changes go in your handoff tool, the tools that save case details, and the code that builds the desk screen.
Build the summary from the fields
In the sample, the summary is not stored anywhere. It is a read-only
property that renders the other sections each time it is read. This excerpt
is the property from handoffpkg/schema.py, with its source indentation.
It is trimmed: the docstring’s last paragraph, about the project’s
requirements document, is left out.
    @property
    def summary(self) -> str:
        """Human-readable summary, DERIVED on every access.

        Not a field. Not settable. Not cached. Every read re-renders from
        ``identity`` / ``intent`` / ``attempts`` / ``do_not_repeat``, so the
        summary and the structured fields are the same information in two
        renderings and cannot drift. Change a field and the next read of
        ``summary`` reflects it; there is no second copy to forget to update.
        """
        return render_summary(self)
Two tests hold this in place. One tries to set the summary and expects an error. The other adds a fake summary to a saved package, saying the caller is verified at tier high. When the package is read back, the fake text is gone and the summary still shows tier medium.
The same rule is taught in the deriving-a-document tutorial’s chapter on derived rendering.
Map each desk question to a field
Next, write down which field answers which question. The sample keeps this
as a mapping in handoffpkg/desk.py:
_QUESTION_RETIRED_BY: dict[str, str] = {
    "Can I take your name?": "identity.display_name",
    "Can you confirm your date of birth?": "identity.verified_tier",
    "Which account is this about?": "intent.details.account_id",
    "What are you calling about today?": "intent.goal",
    "Have you tried anything already?": "attempts",
}
A function in the same file walks this map for each package and lists the questions the desk still has to ask. A small rule per field decides whether it counts as filled:
| Desk question | Answered by | Still asked when |
|---|---|---|
| Can I take your name? | the caller’s name | the name is empty |
| Can you confirm your date of birth? | the verification tier | the tier is unverified |
| Which account is this about? | the account id | no account id crossed |
| What are you calling about today? | the goal | the goal is empty or unknown |
| Have you tried anything already? | the list of attempts | the list is empty, even if the true answer is “no” |
The date of birth question is answered by how strongly identity was checked. The desk never needs the date itself.
Make the screen and the check read the same source. On the agent path run, the screen’s “Do not ask” list leaves out “Have you tried anything already?”. The check counts it as answered. The list shows questions a tool recorded as text, while the check reads the fields.
Save each fact where the handoff collects it
The charge goes missing because two tools use different names for it. The guide to measuring a handoff shows a one-tool fix, which we tested. The dispute tool also saves the amount, merchant and date, under the keys the transfer tool already collects.
With it, all 41 tests pass, and the screen gains the charge, as shown at the top. In your own project, change whichever tool records the case details. The guide to deriving test fixtures from production code covers an earlier gap of the same kind in this sample, and how to catch it.
The check still does not ask about the charge. To make it ask, the sample needs three more changes, which we have not tried:
- Add “Which charge is it?” to the desk’s opening questions.
- Add its entry to the question map. A question with no map entry raises an error on every transfer.
- Add a rule for it in the desk’s per-field check. The check treats a field it does not know as unanswered.
Name what was withheld
Some values must not reach the desk, such as a one-time code or a PIN. But
a missing credential and a held-back one look the same on the screen. So the
sample sends the names of withheld fields, never their values. This is the
setting and its comment in handoffpkg/redaction.py:
# Keys whose *names* are still useful to the desk even though their values must
# not cross. Naming them lets the summary say "withheld by policy" rather than
# leaving the desk to wonder, and stops an agent asking the caller to repeat a
# credential the system already has.
ANNOUNCE_WITHHELD = True
On the agent path run, the screen ends by naming otp_code and
pin_attempt, with “Do not ask the caller to read these out to you.” A test
plants seven sensitive values. Every name reaches the withheld list, and the
planted PIN appears nowhere in the saved package.
Give the reason line a writer
The transfer tool is offered only once the reason line, handoff_reason,
has a value. In the Rasa source we read, the model cannot write project
fields like this one, and nothing in the sample writes it. Add a tool that
composes it from fields. We have not built or tested that tool.
Check the promise
Two facts from the Rasa source, in 3.20.0rc1 and 3.21.0.dev5, change how you test the sentence:
- Spoken before the transfer runs: the skill attaches it as the confirmation for the transfer tool. The confirmation code says the tool “is never invoked here”, only after the model confirms.
- Maybe not the sentence the caller hears: the response sets
rephrase: true. The Rasa source describes that as rewording the text through a separate model call.
This excerpt is the start of skills/human_handoff/responses.yml, trimmed
to the first response:
# Confirmation wording for the handoff. The promise made here — "you will not
# need to repeat yourself" — is one the context package has to actually keep,
# and tests/test_handoff_context.py is what keeps it honest.
responses:
  utter_confirm_handoff:
    - text: >-
        I'll bring in a specialist and pass them everything we've covered, so you
        won't need to repeat any of it. Shall I go ahead?
      metadata:
        rephrase: true
“Everything we’ve covered” promises the whole conversation. The check covers five questions.
This guide recommends narrowing the sentence to what the fields carry. The cost is a smaller promise. A proposed rewording, not tested in the sample:
I’ll pass the specialist your details, what you’re calling about and what we’ve already tried, so you won’t have to go through it again. Shall I go ahead?
When the desk still has a step left, say so. For this dispute case only, you might add: “They’ll need to complete one extra security check before they can raise the dispute.” Widen the question list as you add fields.
The line after the transfer needs the same care. This excerpt is part of
the transfer tool’s result, from skills/human_handoff/tools.py:
            "withheld_fields": list(package.withheld_fields),
            "desk_still_needs_to_ask": list(unanswered_questions(package)),
            "freetext_risk": freetext_risk,
            "hint": (
                "Context package delivered. Tell the caller the handoff id and "
                "that they will not need to repeat themselves. Do not read back "
                "any withheld field."
            ),
The hint repeats the promise whatever the list of open questions holds, and so does the skill’s closing instruction. Make your closing line depend on the list. If it names a question, tell the caller the specialist may ask it.
How to check the fix works
Work in a throwaway copy of the pattern. The transfer tool writes each
package it builds as a JSON file into fixtures/desk_queue.
Run the sample’s tests
From the pattern folder, run the unit tests. They need Python 3 and no Rasa
install. The make test target runs the same command.
With make
make testWithout make
python3 -m unittest discover -s tests -vYou should see 41 tests and OK. We ran the second command with the
system Python 3.9.6, with no Rasa installed.
Render and read the screen from your agent’s own tools
Call your real tools in order, then your transfer tool, and print the desk screen. The script below does this for the sample. Find the line that answers each desk question. Then look for anything the caller said that has no line at all.
Compare it with the demo screen
Run the side by side comparison from the pattern folder:
- Any system
make compare
Its full screen comes from a session typed by hand, and it shows the dispute amount, merchant and date. The agent’s own tools did not produce those until the fix. Review only screens your tools produced.
Show the script behind the agent path run
The script calls the sample’s tools directly, with a stand-in for memory and
no model, network or licence. It types in the charge and the reason line. It
writes one package file into fixtures/desk_queue. Its module docstring is
left out here.
import asyncio
import importlib.util
import sys
from pathlib import Path

ROOT = Path.cwd()
sys.path.insert(0, str(ROOT))


def load(path, name):
    spec = importlib.util.spec_from_file_location(name, ROOT / path)
    module = importlib.util.module_from_spec(spec)
    spec.loader.exec_module(module)
    return module


class Memory(dict):
    def set(self, key, value):
        self[key] = value


class Context:
    def __init__(self):
        self.memory = Memory()


dispute = load("skills/dispute_transaction/tools.py", "dispute_tools")
handoff = load("skills/human_handoff/tools.py", "handoff_tools")


async def main():
    ctx = Context()
    await dispute.load_caller_context(context=ctx)
    await dispute.list_recent_charges(context=ctx)
    ctx.memory.set("disputed_txn_id", "txn_c101")  # typed: the caller's choice
    await dispute.raise_dispute(context=ctx)
    ctx.memory.set(
        "handoff_reason",
        "Dispute needs a second factor the caller cannot complete on this line.",
    )  # typed: nothing on the live path at 3.20.0rc1 sets handoff_reason

    print("attempts_log as written by the dispute tools:")
    print(ctx.memory["attempts_log"])
    print("disputed_txn_label in memory:", ctx.memory.get("disputed_txn_label"))
    print("disputed_txn_label in _MEMORY_KEYS:", "disputed_txn_label" in handoff._MEMORY_KEYS)
    print("dispute_date in memory:", "dispute_date" in ctx.memory)

    result = await handoff.transfer_to_human(context=ctx)
    r = result.llm_response
    print("withheld_fields:", r["withheld_fields"])
    print("desk_still_needs_to_ask:", r["desk_still_needs_to_ask"])
    print("hint:", r["hint"])
    print()
    print(r["_desk_preview"])


asyncio.run(main())
The last comment names the version we first ran. We read the same in the
3.21.0.dev5 source. Save the script as scripts/agent_path_screen.py.
It needs a Python with rasa-pro installed. In the pattern folder, make install uses uv to create a .venv folder with the version the pattern
pins. Then run, from the pattern folder:
.venv/bin/python scripts/agent_path_screen.pyWe did not use make install. We ran the same script with another
virtualenv’s Python 3.12, which had rasa-pro 3.21.0.dev5. The environment
held only HOME, PATH and PYTHONDONTWRITEBYTECODE=1.
This is its output before the fix, unedited. The handoff id is random on each run.
attempts_log as written by the dispute tools:
verify_passphrase|succeeded||Caller answered the knowledge factor on the first try.
send_otp_sms|failed|delivery_failed|Carrier rejected the SMS twice. Do not resend to this number.
raise_dispute|blocked|insufficient_tier|Dispute needs tier 'high'; caller is at 'medium'.
disputed_txn_label in memory: Northgate Fuel $248.00
disputed_txn_label in _MEMORY_KEYS: False
dispute_date in memory: False
withheld_fields: ['otp_code', 'pin_attempt']
desk_still_needs_to_ask: []
hint: Context package delivered. Tell the caller the handoff id and that they will not need to repeat themselves. Do not read back any withheld field.

========================================================================
INBOUND HANDOFF ho_62186e0c — Dispute needs a second factor the caller cannot complete on this line.
========================================================================
CALLER      Jordan Rivera (cust_00417) via voice
TRUST       tier=medium — Verified with a knowledge factor. Account-specific information is in scope.
ASKING FOR  Dispute a card transaction [account_id=acc_checking, account_label=Everyday Checking, card_last_four=4821] (stage: blocked)

ALREADY TRIED (do not retry these):
  · verify_passphrase → succeeded (Caller answered the knowledge factor on the first try.)
  · send_otp_sms → failed (Carrier rejected the SMS twice. Do not resend to this number.)
  · raise_dispute → blocked (Dispute needs tier 'high'; caller is at 'medium'.)

DO NOT ASK — the caller already answered these:
  · Can I take your name?
  · Can you confirm your date of birth?
  · Which account is this about?
  · What are you calling about today?
  · verified: knowledge_passphrase
  · confirmed: Caller consented to the call being recorded.

YOU MAY:
  · Answer general questions
  · Explain what the agent already did
  · Discuss account-specific details
  · DO NOT action irreversible changes — step the caller up first

WITHHELD BY POLICY (present in the session, not transferred):
  · otp_code
  · pin_attempt
  Do not ask the caller to read these out to you.
========================================================================
Trade-offs
A computed screen reads like a form. It carries only what a field can hold, so a remark such as “she sounded frightened” does not cross. In the sample, a tool writes every text field that crosses, apart from the reason line. So the wording of those fields is part of your design.
Limits
- Every run here is offline: the package, the tools and a test desk. None of it shows what a model says on a live call.
- These claims rest on reading source, not on a run:
- when the promise is spoken, and that it may be reworded;
- that nothing on the live path sets the reason line;
- that a question with no map entry raises an error;
- that the check treats a field it does not know as unanswered;
- that the hint and the skill’s closing instruction promise no repeats whatever the check returns.
- We first ran the tools on Rasa Pro 3.20.0rc1 at revision
69e27b6, then on 3.21.0.dev5, the version this site pins, at4aa0c44. Only the random handoff id changed. The fix was tested on one charge. - The allowlist is a design boundary, not a compliance control. The pattern says it does not redact the call recording, the transcript or earlier logs.
- The test desk is a local folder, and the caller and account are test values. Whether a real contact-centre system accepts the case is not tested.
Questions you will hit
Should the assistant read the desk screen back to the caller?
No. A comment in the tool says the screen is returned so the agent can “honestly tell the caller what was passed on”. It adds: “never so it can read it back to them”. Reading it aloud could also speak account details to whoever is on the line. Give the handoff id and what happens next instead.